---
license: apache-2.0
base_model: 3DAIGC/LAM_audio2exp
library_name: onnxruntime
tags:
- onnx
- audio2expression
- arkit
- blendshapes
- facial-animation
- avatar
- wav2vec2
- realtime
- cpu
---
# Wav2ARKit - Audio to Facial Expression (ONNX)
A **fused, end-to-end ONNX model** that converts raw audio waveforms directly into 52 ARKit-compatible facial blendshapes. Based on the [Facebook Wav2Vec2](https://huggingface.co/facebook/wav2vec2-base-960h) and [LAM Audio2Expression](https://huggingface.co/3DAIGC/LAM_audio2exp) models, optimized for real-time CPU inference.
## Features
| Feature | Value |
|---------|-------|
| **Input** | Raw 16kHz audio waveform |
| **Output** | 52 ARKit blendshapes @ 30fps |
| **Inference** | ~45ms per second of audio |
| **Speed** | 22× faster than realtime |
| **Size** | 1.8 MB |
## Quick Start
```python
import onnxruntime as ort
import numpy as np
# Load model
session = ort.InferenceSession("wav2arkit_cpu.onnx", providers=["CPUExecutionProvider"])
# Load audio (16kHz, mono, float32)
# Example: 1 second = 16000 samples
audio = np.random.randn(1, 16000).astype(np.float32)
# Output: (1, 30, 52) - 30 frames at 30fps, 52 blendshapes
```
## Model Specification
### Input
| Name | Type | Shape | Description |
|------|------|-------|-------------|
| `audio_waveform` | float32 | `[batch, samples]` | Raw audio at 16kHz |
### Output
| Name | Type | Shape | Description |
|------|------|-------|-------------|
| `blendshapes` | float32 | `[batch, frames, 52]` | ARKit blendshapes [0-1] |
### Frame Calculation
```
output_frames = ceil(30 × (num_samples / 16000))
```
Example: 1 second audio (16000 samples) → 30 frames
## ARKit Blendshapes
52 blendshape indices (click to expand)
| Idx | Name | Idx | Name |
|-----|------|-----|------|
| 0 | browDownLeft | 26 | mouthClose |
| 1 | browDownRight | 27 | mouthDimpleLeft |
| 2 | browInnerUp | 28 | mouthDimpleRight |
| 3 | browOuterUpLeft | 29 | mouthFrownLeft |
| 4 | browOuterUpRight | 30 | mouthFrownRight |
| 5 | cheekPuff | 31 | mouthFunnel |
| 6 | cheekSquintLeft | 32 | mouthLeft |
| 7 | cheekSquintRight | 33 | mouthLowerDownLeft |
| 8 | eyeBlinkLeft | 34 | mouthLowerDownRight |
| 9 | eyeBlinkRight | 35 | mouthPressLeft |
| 10 | eyeLookDownLeft | 36 | mouthPressRight |
| 11 | eyeLookDownRight | 37 | mouthPucker |
| 12 | eyeLookInLeft | 38 | mouthRight |
| 13 | eyeLookInRight | 39 | mouthRollLower |
| 14 | eyeLookOutLeft | 40 | mouthRollUpper |
| 15 | eyeLookOutRight | 41 | mouthShrugLower |
| 16 | eyeLookUpLeft | 42 | mouthShrugUpper |
| 17 | eyeLookUpRight | 43 | mouthSmileLeft |
| 18 | eyeSquintLeft | 44 | mouthSmileRight |
| 19 | eyeSquintRight | 45 | mouthStretchLeft |
| 20 | eyeWideLeft | 46 | mouthStretchRight |
| 21 | eyeWideRight | 47 | mouthUpperUpLeft |
| 22 | jawForward | 48 | mouthUpperUpRight |
| 23 | jawLeft | 49 | noseSneerLeft |
| 24 | jawOpen | 50 | noseSneerRight |
| 25 | jawRight | 51 | tongueOut |
## Usage Examples
### Python with audio file
```python
import onnxruntime as ort
import numpy as np
import soundfile as sf
session = ort.InferenceSession("wav2arkit_cpu.onnx", providers=["CPUExecutionProvider"])
# Load and resample audio to 16kHz if needed
audio, sr = sf.read("speech.wav")
if sr != 16000:
import librosa
audio = librosa.resample(audio, orig_sr=sr, target_sr=16000)
# Ensure mono
if len(audio.shape) > 1:
audio = audio.mean(axis=1)
# Run inference
audio_input = audio.astype(np.float32).reshape(1, -1)
blendshapes = session.run(None, {"audio_waveform": audio_input})[0]
print(f"Duration: {len(audio)/16000:.2f}s → {blendshapes.shape[1]} frames")
```
### C++
```cpp
#include
Ort::Env env(ORT_LOGGING_LEVEL_WARNING, "Wav2ARKit");
Ort::Session session(env, L"wav2arkit_cpu.onnx", Ort::SessionOptions{});
std::vector audio(16000); // 1 second
std::vector shape = {1, 16000};
Ort::MemoryInfo mem = Ort::MemoryInfo::CreateCpu(OrtArenaAllocator, OrtMemTypeDefault);
Ort::Value input = Ort::Value::CreateTensor(mem, audio.data(), audio.size(), shape.data(), shape.size());
const char* input_names[] = {"audio_waveform"};
const char* output_names[] = {"blendshapes"};
auto output = session.Run({}, input_names, &input, 1, output_names, 1);
```
### JavaScript (onnxruntime-web/node)
```javascript
const ort = require('onnxruntime-node');
const session = await ort.InferenceSession.create('wav2arkit_cpu.onnx');
const audioTensor = new ort.Tensor('float32', audioData, [1, audioData.length]);
const { blendshapes } = await session.run({ audio_waveform: audioTensor });
```
## Architecture
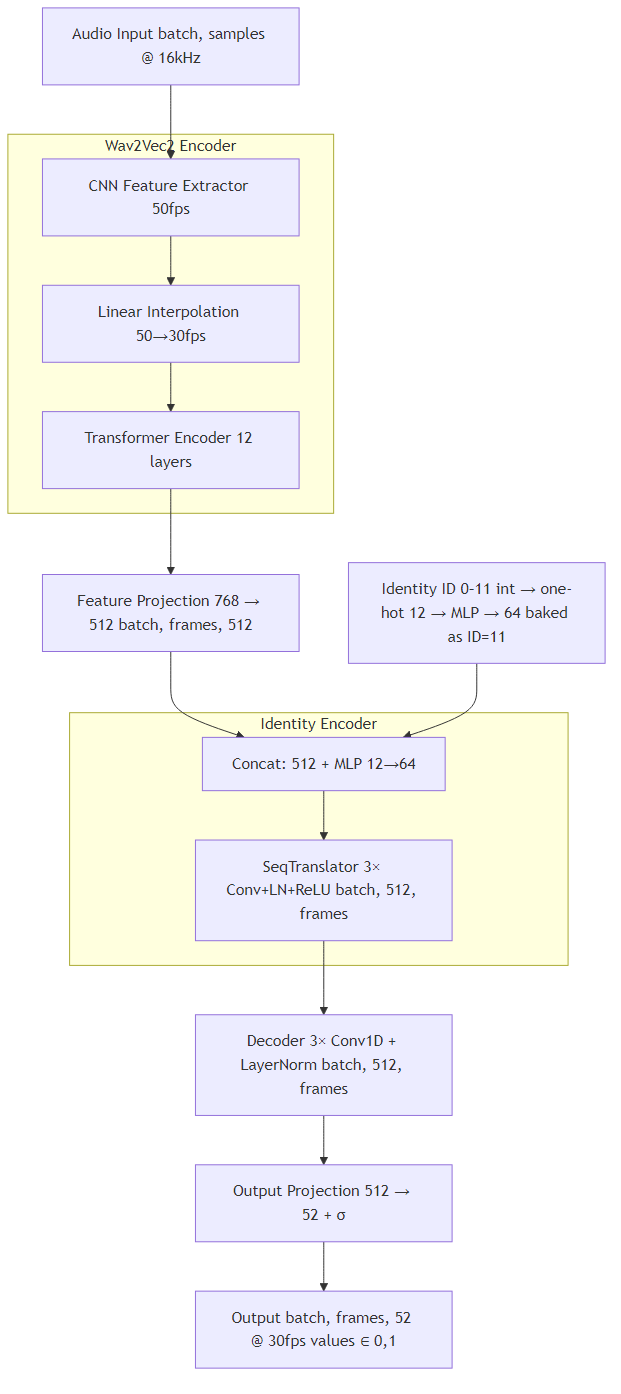
**Note:** The identity encoder supports 12 speaker identities (0-11). This ONNX export uses identity `11` baked in for single-speaker inference.
## License
Apache 2.0 - Based on:
- [3DAIGC/LAM_audio2exp](https://huggingface.co/3DAIGC/LAM_audio2exp)
- [facebook/wav2vec2-base-960h](https://huggingface.co/facebook/wav2vec2-base-960h)